Introduction
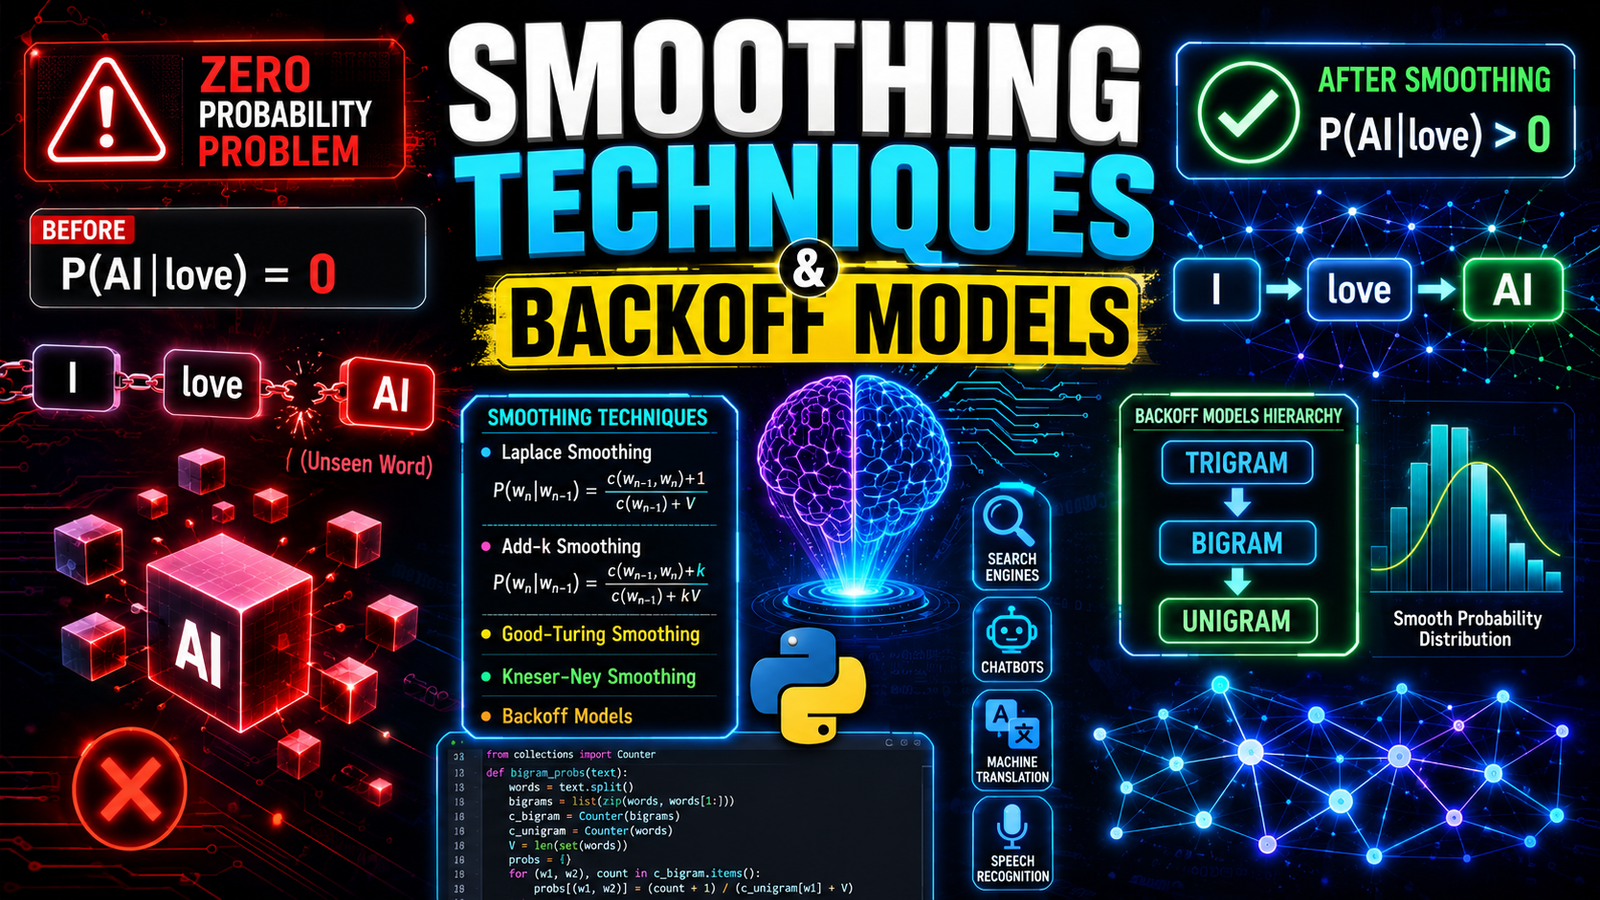
In the previous lecture, we learned about Language Models and N-grams. One major challenge in N-gram Language Models is the Data Sparsity Problem.
Many word combinations never appear in training data. When this happens, the probability of that word sequence becomes zero.
This problem can seriously affect the performance of:
- Search Engines
- Machine Translation Systems
- Chatbots
- Speech Recognition Systems
- Text Prediction Applications
To solve this issue, NLP uses Smoothing Techniques and Backoff Models.
Learning Outcomes
After completing this lecture, students will be able to:
- Understand the Zero Probability Problem.
- Explain different Smoothing Techniques.
- Implement Laplace Smoothing in Python.
- Differentiate between Add-k, Good-Turing, and Kneser-Ney methods.
- Understand Backoff Models.
- Apply smoothing techniques in NLP applications.
The Zero Probability Problem
Consider the following training corpus:
I love NLP
I love Python
I study NLP
Suppose we want to calculate:
Probability of:
love AI
Since "love AI" never appeared in training data:
P(AI∣love)=0
As a result, the probability of the entire sentence becomes zero.
This issue is known as the Zero Probability Problem.
Why is Zero Probability a Problem?
Imagine a chatbot receives:
I love Artificial Intelligence
If "Artificial Intelligence" never appeared in training data, the language model may incorrectly assume the sentence is impossible.
This reduces:
- Prediction accuracy
- Translation quality
- Chatbot performance
- Search relevance
What is Smoothing?
Smoothing is a technique that assigns a small non-zero probability to unseen events.
Instead of:
Probability = 0
We assign:
Probability > 0
Benefits:
- Handles unseen words
- Improves language models
- Reduces data sparsity issues
- Enhances prediction accuracy
Types of Smoothing Techniques
1. Laplace Smoothing (Add-One Smoothing)
The simplest smoothing method.
Rule:
Add 1 to every frequency count.
Formula:

Where:
- Count = Frequency
- V = Vocabulary Size
Example of Laplace Smoothing
Suppose:
Count(I love) = 50
Count(I) = 100
Vocabulary Size = 500
Then:

Result:
0.085
Python Example: Laplace Smoothing
from collections import Counter

text = "I love NLP I love Python I study NLP"

words = text.split()

vocabulary = set(words)
V = len(vocabulary)

bigrams = []

for i in range(len(words)-1):
    bigrams.append((words[i], words[i+1]))

bigram_counts = Counter(bigrams)

count_bigram = bigram_counts[('love', 'Python')]
count_unigram = words.count('love')

probability = (count_bigram + 1) / (count_unigram + V)

print("Laplace Probability =", probability)
Output
Laplace Probability = 0.2857
Advantages of Laplace Smoothing
- Easy to implement
- Eliminates zero probabilities
- Useful for small datasets
Disadvantages
- Overestimates unseen events
- Can distort actual probabilities
2. Add-k Smoothing
Instead of adding 1, we add a smaller constant value k.
Formula:

Common values:
k = 0.1
k = 0.5
Example
Given:
Count(love Python)=1
Count(love)=2
V=5
k=0.5
Then:

Python Example: Add-k Smoothing
k = 0.5

count_bigram = 1
count_unigram = 2
V = 5

probability = (count_bigram + k) / (count_unigram + k * V)

print("Add-k Probability =", probability)
Why Add-k is Better than Laplace?
Laplace adds too much probability mass.
Add-k:
- More flexible
- More realistic
- Better performance
3. Good-Turing Smoothing
Good-Turing Smoothing estimates probabilities of unseen events using rare events.
Main Idea:
Events occurring once provide information about unseen events.
Example:

The model redistributes probability from common events to unseen events.
Advantages
- Better handling of unseen data
- Effective for sparse datasets
Disadvantages
- Complex calculations
- Difficult implementation
4. Kneser-Ney Smoothing
One of the most advanced smoothing techniques.
Widely used in:
- Google Search
- Speech Recognition
- Machine Translation
- NLP Research
Features:
- Uses lower-order probabilities
- Produces better estimates
- Handles rare words effectively
Comparison of Smoothing Techniques

What are Backoff Models?
Backoff Models solve missing N-gram problems.
If a higher-order N-gram does not exist, the model "backs off" to a lower-order N-gram.
Example:
Suppose Trigram:
I love AI
is unavailable.
Then use Bigram:
love AI
If Bigram is unavailable:
Use Unigram:
AI
Backoff Hierarchy
Trigram
   ↓
Bigram
   ↓
Unigram
Mathematical Representation
If Trigram exists:

Katz Backoff Model
Katz Backoff is the most popular backoff method.
Working:
- Check Trigram
- If unavailable → Bigram
- If unavailable → Unigram
Advantages:
- Efficient
- Handles sparse data
- Better than simple N-grams
Python Example: Simple Backoff Model
bigram_probs = {
    ('I', 'love'): 0.8,
    ('love', 'Python'): 0.7
}

unigram_probs = {
    'Python': 0.2,
    'AI': 0.1
}

query = ('love', 'AI')

if query in bigram_probs:
    print("Bigram Found")
    print(bigram_probs[query])
else:
    print("Backing Off To Unigram")

    word = 'AI'
    probability = unigram_probs.get(word, 0.01)

    print(probability)
Output
Backing Off To Unigram
0.1
Stupid Backoff Model
Google introduced Stupid Backoff for large-scale systems.
Formula:

Interpolation vs Backoff

Real-World Applications
Search Engines
Predict user search queries.
Example:
Best AI ______
Suggestions:
- tools
- software
- courses
Mobile Keyboards
Predict next word while typing.
Voice Assistants
Examples:
- Siri
- Alexa
- Google Assistant
Chatbots
Generate more natural responses.
Machine Translation
Improve translation quality.
Advantages of Smoothing & Backoff Models
- Solves zero probability problem
- Improves prediction accuracy
- Handles unseen words
- Reduces sparsity issues
- Better language generation
Limitations
- Complex calculations
- Computational overhead
- Requires parameter tuning
- Large datasets needed for best results
Summary
In this Topic, we learned:
✅ Zero Probability Problem
✅ Data Sparsity
✅ Laplace Smoothing
✅ Add-k Smoothing
✅ Good-Turing Smoothing
✅ Kneser-Ney Smoothing
✅ Backoff Models
✅ Katz Backoff
✅ Stupid Backoff
✅ Python Implementations
Conclusion
Smoothing Techniques and Backoff Models are essential for building robust NLP systems. They solve the data sparsity problem by assigning probabilities to unseen events and using lower-order N-grams when necessary. These techniques form the foundation of modern language modeling and continue to play an important role in search engines, chatbots, machine translation, and AI-powered applications.